Harvest Now, Decrypt Later: Why Post-Quantum Migration Cannot Wait Until Quantum Computers Arrive
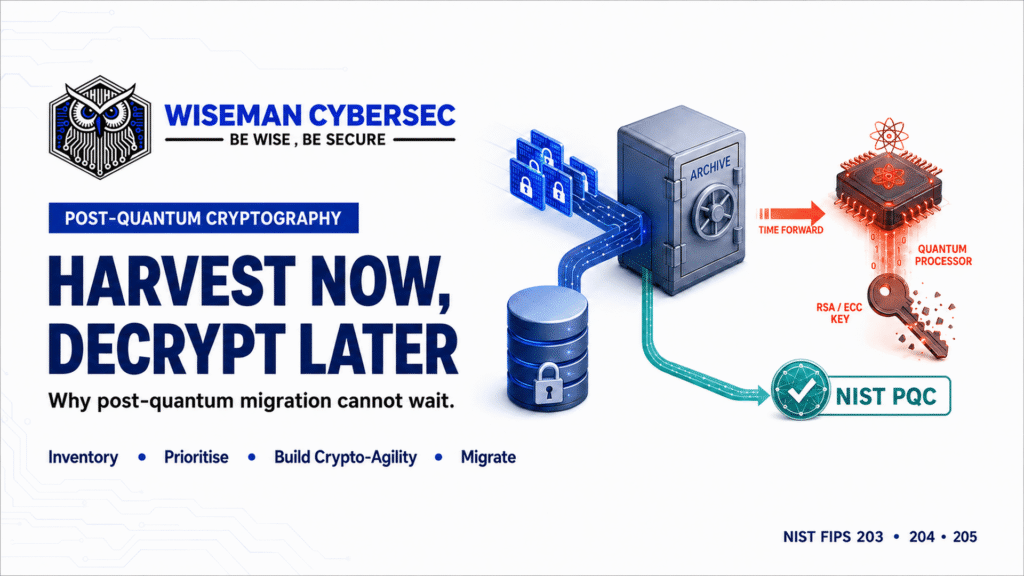
Some cybersecurity risks become urgent only after the technology behind them becomes available. Post-quantum risk is different. Sensitive information can be stolen today, stored for years and decrypted later when sufficiently capable quantum computers become available. By that point, changing the encryption algorithm will protect future data—but it will not restore the confidentiality of information already collected. This threat is known as Harvest Now, Decrypt Later, or HNDL. For organisations handling long-life health records, identity data, financial information, government communications, intellectual property or strategic business information, the post-quantum deadline may have already started. What Is “Harvest Now, Decrypt Later”? In an HNDL attack, an adversary does not need to break encryption immediately. The attacker may: Today, strong cryptography may prevent the attacker from reading that information. However, the attacker can preserve the ciphertext until more powerful computing capabilities become available. A cryptographically relevant quantum computer could eventually threaten widely used public-key algorithms based on integer factorisation and discrete logarithms. These include RSA, Diffie-Hellman, elliptic-curve Diffie-Hellman and elliptic-curve digital signatures. NIST specifically identifies sensitive or long-lived data protected by quantum-vulnerable cryptography as being exposed to the The attack therefore begins when the encrypted information is collected—not when quantum decryption finally becomes possible. Why Long-Life Data Creates an Immediate Risk Not every piece of information has the same confidentiality period. A promotional email may lose its value within weeks. A customer password can be changed. But other information may remain sensitive for ten, twenty or even thirty years. Examples include: If this information is stolen today and must remain confidential beyond the useful life of its current encryption, the organisation already has a post-quantum exposure. This is why quantum readiness cannot be based only on predicting when a powerful quantum computer will arrive. That date remains uncertain. The more important question is: How long must the data remain confidential, and how long will the organisation need to complete its migration? If the combined data-protection period and migration time extend into the possible quantum-risk window, waiting is not a safe strategy. Quantum Risk Is Not Limited to Decryption Post-quantum discussions often focus only on encrypted data. However, public-key cryptography also protects digital trust. Digital signatures are used to verify software updates, certificates, transactions, documents, devices, users and code. If quantum-vulnerable signature algorithms are compromised, attackers may be able to forge trusted identities or malicious content. Potential consequences include: Post-quantum migration must therefore address both sides of public-key cryptography: Simply replacing an encryption library in one application will not solve the wider problem. NIST’s Post-Quantum Cryptography Standards In August 2024, NIST published its first three principal post-quantum cryptography standards. NIST now states that these algorithms can and should be put into use as organisations begin their migration. ML-KEM — FIPS 203 ML-KEM is a module-lattice-based key-encapsulation mechanism. It allows two parties to establish a shared secret over a public channel. That shared secret can then be used with symmetric cryptography to protect communications. ML-KEM is intended to address quantum risk in key-establishment scenarios such as secure communication protocols, VPNs and other encrypted connections. ML-DSA — FIPS 204 ML-DSA is a module-lattice-based digital-signature algorithm. It is designed to protect the authenticity and integrity of digital information and is expected to support many post-quantum signature deployments. SLH-DSA — FIPS 205 SLH-DSA is a stateless hash-based digital-signature algorithm. Because it is based on a different mathematical approach, it provides an alternative to ML-DSA for appropriate use cases and contributes to cryptographic diversity. These standards provide a foundation, but publishing an algorithm is not the same as completing an enterprise migration. Products, protocols, applications, certificates, hardware and vendor services must all be updated and tested. Migration Begins With a Cryptographic Inventory An organisation cannot migrate cryptography it cannot locate. Cryptographic functions may exist across applications, APIs, cloud services, certificates, VPNs, databases, identity systems, hardware security modules, embedded devices, source code and third-party platforms. Some implementations are visible and centrally managed. Others may be buried inside legacy applications, vendor products or undocumented dependencies. A useful cryptographic inventory should identify: NIST’s National Cybersecurity Center of Excellence is specifically working on cryptographic discovery tools and inventories to help organisations locate quantum-vulnerable cryptography and prioritise migration decisions. The inventory should not be treated as a one-time spreadsheet. It must become part of continuing security architecture, asset management and procurement processes. Prioritise According to Risk, Not Convenience Attempting to replace every cryptographic implementation simultaneously would create unnecessary operational risk. Migration should be prioritised according to: Systems protecting long-life sensitive information should receive early attention. Organisations should also prioritise long-lived infrastructure such as public-key infrastructure, code-signing systems, identity platforms, VPNs, TLS environments, hardware devices and operational technology. These systems may remain deployed for many years and can be difficult to replace quickly. Crypto-Agility Must Become an Architectural Requirement Post-quantum migration should not result in another generation of systems permanently tied to a single algorithm. Algorithms may be weakened, standards may evolve and implementation defects may be discovered. Organisations must be able to change cryptographic components without rebuilding entire systems or causing lengthy service interruptions. NIST defines crypto-agility as the capability to replace and adapt cryptographic algorithms across protocols, applications, software, hardware, firmware and infrastructure while preserving security and ongoing operations. Its guidance was most recently updated in June 2026. Practical crypto-agility may include: Crypto-agility is not merely a post-quantum control. It strengthens the organisation’s ability to respond to any future cryptographic vulnerability or transition. A Practical Post-Quantum Migration Roadmap Organisations do not need to replace every algorithm immediately. They do need a structured programme. 1. Establish ownership Assign responsibility for post-quantum readiness across security, architecture, infrastructure, application development, risk, compliance and procurement teams. 2. Build the cryptographic inventory Identify where RSA, Diffie-Hellman, ECC and other quantum-vulnerable public-key mechanisms are used across internal and third-party environments. 3. Classify data by protection lifetime Determine which information must remain confidential for years or decades. Prioritise data with long-term legal, strategic, financial or personal value. 4. Assess vendor readiness Ask technology providers which NIST-standardised algorithms they support,
AI Agents Are the New Privileged Identities: Is Your IAM Strategy Ready?
For years, organizations have focused on securing human users, service accounts, applications and machines. Now, a new category of identity is entering the enterprise: the AI agent. Unlike traditional AI assistants that mainly generate answers, agentic AI systems can reason, make decisions, access applications, retrieve sensitive data, call APIs and execute actions with limited human involvement. An AI agent may soon be able to: This capability can deliver significant productivity improvements. It can also create a new class of highly privileged, autonomous identities. The question is no longer only, “Is the AI model secure?” Organizations must also ask:Who is the agent, what is it permitted to access, who is responsible for it and how can its authority be withdrawn? From Model Risk to Action Risk Traditional generative AI security often focuses on risks such as prompt injection, sensitive-information disclosure, insecure output handling and data poisoning. Agentic AI expands the problem. An agent does not simply produce content. It can translate that content into action by using tools, credentials, APIs and enterprise applications. A manipulated chatbot may provide an incorrect response. A manipulated AI agent could change a configuration, disclose sensitive information, delete data or execute an unauthorized transaction. This is the difference between model risk and action risk. The greater an agent’s autonomy, connectivity and access privileges, the greater its potential blast radius. Recognizing this shift, NIST launched its AI Agent Standards Initiative in 2026 and began examining how established identity and authorization practices can be applied to software and AI agents. OWASP’s Top 10 for Agentic Applications also highlights risks such as agent goal hijacking, tool misuse, identity and privilege abuse, memory poisoning, insecure agent communication and rogue-agent behaviour.Agent security is quickly becoming an identity-security challenge. Why Every AI Agent Needs Its Own Identity An agent should never operate as an invisible extension of a human account or through a shared, permanently privileged credential. Every production AI agent should have a unique and verifiable identity. That identity should establish: Separate identities make it possible to enforce least privilege, monitor behaviour, investigate incidents and revoke access without affecting unrelated users or agents. If multiple agents share the same identity, security teams may be unable to determine which agent performed an action or whether it was initiated by a user, an agent or a compromised integration.Accountability begins with identity. Five Identity Risks Created by AI Agents 1. Excessive privileges Agents are often given broad access because developers want them to complete workflows without interruptions. An agent that only needs to read support tickets should not be able to delete them. An agent that recommends cloud changes should not automatically have permission to deploy those changes. Convenience must not replace least privilege. 2. Agent sprawl Business teams may create AI agents faster than security and IT teams can discover or govern them. Without a central inventory, organizations can accumulate unknown, duplicated or abandoned agents connected to sensitive systems. This resembles service-account sprawl, but with an added layer of autonomy. 3. Shared or inherited credentials An agent may inherit the permissions of its creator or use a shared API key. If the agent is compromised, an attacker may gain the same access. Long-lived credentials also make revocation and attribution more difficult. 4. Goal hijacking and tool misuse Malicious instructions hidden inside emails, documents, websites or external data can influence an agent’s behaviour. If the agent can access powerful tools, manipulated instructions may lead to unauthorized data retrieval, message sending, code execution or configuration changes. 5. Incomplete audit trails Traditional logs may record that an API was called without explaining which agent initiated it, which user request triggered the action or what information influenced the decision. Security teams need visibility across the complete chain: Human request → Agent decision → Tool invocation → System action → Business outcomeWithout this context, investigation and accountability become extremely difficult. Building an Identity-First Security Model for AI Agents Organizations do not need to abandon their existing security foundations. They need to extend them to autonomous systems. A practical identity-first approach should include the following controls. Discover and classify every agent Maintain a central inventory of production and experimental agents. Record the agent’s owner, purpose, environment, connected systems, data access, model, tools and operational risk. Assign a unique identity Every agent should have its own managed identity rather than using a shared account or impersonating its creator. The organization must be able to distinguish between: Enforce least-privilege access Access should be limited by task, resource, environment, time and risk. An agent should receive only the permissions required for its approved purpose. Privileged access should be temporary wherever possible. Introduce approval gates High-impact activities should require explicit human approval. These may include: Autonomy should be proportional to risk. Protect credentials and tokens API keys, secrets and access tokens should be stored in approved secrets-management systems, rotated regularly and prevented from appearing in prompts, memory or logs. Short-lived credentials are preferable to permanent access. Monitor agent behaviour Security teams should establish normal behaviour for each agent and detect unusual actions, access patterns, tool usage or data movement. Logs should capture the agent identity, initiating user, requested objective, tools invoked, resources accessed and final action. Govern the complete lifecycle Agents should be provisioned, reviewed and decommissioned through a controlled lifecycle. When an owner leaves, a project ends or an agent is no longer required, its credentials and access must be revoked immediately. Test before granting autonomy Organizations should evaluate agents for prompt injection, excessive agency, tool misuse, data leakage, privilege escalation and unexpected behaviour before production deployment. Security testing must cover the complete agent workflow—not only the underlying model. Questions Leaders Should Ask Today Before deploying an AI agent, security and business leaders should be able to answer: If these questions cannot be answered, the agent is not ready for unrestricted enterprise access. The Next IAM Challenge Has Already Arrived AI agents are becoming part of the enterprise workforce, but they cannot be governed exactly like employees or treated merely as
5 AI Governance Frameworks, Laws and Standards Every AIGP Candidate Should Know in 2026
Artificial intelligence adoption is accelerating faster than many organisations can establish effective governance. Bain reported in 2025 that 95% of surveyed US companies were using generative AI. The research also found that the average number of production use cases had doubled between October 2023 and December 2024. This growth creates enormous opportunities, but it also introduces risks involving privacy, cybersecurity, discrimination, transparency, accountability, intellectual property and regulatory compliance. Organisations therefore need more than an AI policy. They need structured ways to identify risks, assign accountability, evaluate impacts and monitor AI systems throughout their lifecycle. For professionals preparing for the IAPP Artificial Intelligence Governance Professional certification, understanding the major AI governance instruments is essential. However, candidates must also recognise an important distinction: A framework, regulation, standard, policy directive and code of conduct are not the same thing.This guide examines five important AI governance instruments and explains how each should be understood. 1. NIST Artificial Intelligence Risk Management Framework The NIST Artificial Intelligence Risk Management Framework, commonly called the NIST AI RMF, was released in January 2023 by the US National Institute of Standards and Technology. It is a voluntary and industry-agnostic framework designed to help organisations manage risks associated with the design, development, deployment and use of AI systems. Rather than providing a rigid compliance checklist, the framework helps organisations establish repeatable processes for trustworthy AI. The NIST AI RMF is structured around four functions: Govern Establish policies, accountability, organisational roles, risk tolerances and oversight mechanisms for AI. Map Understand the purpose, context, stakeholders, potential impacts and operating environment of an AI system. Measure Assess, analyse and track AI risks using appropriate qualitative and quantitative methods. Manage Prioritise identified risks, implement controls, monitor responses and determine whether risks should be accepted, mitigated, transferred or avoided. AIGP Accuracy Note The four official functions are: Govern → Map → Measure → Manage “Monitor” is not a separate NIST AI RMF function. Monitoring activities may support the framework, but the fourth function is officially called Manage. Why it matters The NIST AI RMF helps organisations translate broad responsible-AI principles into practical governance activities. It can be adapted across industries and used alongside privacy, cybersecurity, enterprise-risk and compliance programmes. For AIGP candidates, the important point is to understand both the four functions and the iterative relationship between them. 2. European Union Artificial Intelligence Act The EU AI Act is not a voluntary framework. It is a legally binding regulation governing the development, deployment and use of AI systems within its scope. The Act entered into force on 1 August 2024 and follows a phased implementation timeline. Prohibited AI practices and AI-literacy requirements began applying in February 2025. Obligations concerning general-purpose AI models began applying in August 2025. Most remaining provisions are scheduled to become applicable from 2 August 2026, while certain requirements for high-risk AI systems connected with regulated products follow a later timeline. The Act applies a risk-based regulatory model. Prohibited AI practices Certain practices presenting unacceptable risks to fundamental rights are prohibited. These include specific forms of social scoring, manipulative AI, biometric categorisation and other practices defined by the regulation. The prohibitions are specific. It would be inaccurate to assume that every use of surveillance, biometrics or automated monitoring is automatically banned. High-risk AI systems AI used in sensitive areas such as employment, education, essential services, law enforcement and certain regulated products may be classified as high risk. Depending on the system and the organisation’s role, requirements may include: Transparency obligations Certain AI systems must disclose that users are interacting with AI. Additional transparency requirements may apply to synthetic content, deepfakes and general-purpose AI models. Minimal or no-risk systems Many ordinary AI applications remain largely unaffected, although organisations may still voluntarily adopt codes of conduct and responsible-AI practices. AIGP Accuracy Note The EU AI Act was not adopted in late 2023 and is no longer merely “expected to take effect.” It entered into force in August 2024, and several of its provisions are already applicable. Why it matters The EU AI Act moves AI governance from voluntary principles to enforceable responsibilities. Its influence is also likely to extend beyond Europe because organisations offering AI systems or services in the EU may fall within its scope. AIGP candidates should understand the difference between prohibited practices, high-risk requirements, transparency obligations and general-purpose AI responsibilities. 3. ISO/IEC 42001 and ISO/IEC 23894 ISO and the International Electrotechnical Commission have developed complementary standards for AI governance and risk management. Although they are frequently discussed together, ISO/IEC 42001 and ISO/IEC 23894 serve different purposes. ISO/IEC 42001:2023 ISO/IEC 42001 establishes requirements for an Artificial Intelligence Management System. It helps an organisation build an enterprise-wide system of policies, roles, objectives, processes and controls for the responsible development or use of AI. The standard follows the Plan-Do-Check-Act model commonly used across ISO management-system standards. It addresses areas such as: Because ISO/IEC 42001 is a requirements-based management-system standard, an organisation may pursue certification through an independent certification body. ISO/IEC 23894:2023 ISO/IEC 23894 provides guidance on managing risks specifically associated with AI. It helps organisations integrate AI-related risks into their existing risk-management activities and considers risks affecting organisations, individuals, groups and society. The standard can support AI risk identification, analysis, evaluation, treatment, communication and monitoring. AIGP Accuracy Note ISO/IEC 42001 is an AI management-system requirements standard against which an organisation may be certified. ISO/IEC 23894 is a risk-management guidance document. It is not a management-system certification standard. Why they matter Together, the two standards provide complementary value. ISO/IEC 42001 helps establish the organisational management system, while ISO/IEC 23894 provides deeper guidance for managing AI-specific risks within that system. For AIGP professionals, understanding this distinction is important when advising organisations about governance implementation and certification. 4. OECD Artificial Intelligence Principles The OECD AI Principles were originally adopted in 2019 and updated in May 2024 to address developments involving general-purpose and generative AI. They were the first intergovernmental standard for trustworthy AI and have influenced national policies, international initiatives and other governance instruments. The principles
L1 SOC ANALYST INTERVIEW QUESTION BANK
You Don’t Need 10 Certifications to Get Into Cybersecurity—You Need These 5 Skills
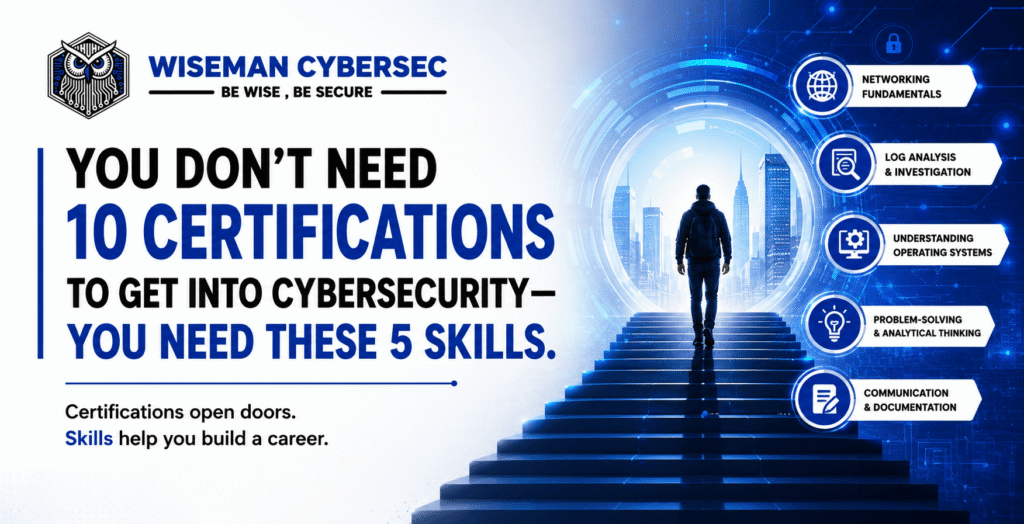
A cybersecurity beginner opens LinkedIn and sees the same advice everywhere. Get certified. Then get another certification. Then another one. Before long, the goal of building a cybersecurity career quietly turns into a race to collect certificates. CEH. Security+. CySA+. CISSP. CISM. ISO 27001. Maybe a few more just to make the resume look stronger. And yet, when the person finally sits in front of a recruiter or enters a real security environment, one simple question can expose the gap: “You have received an alert for multiple failed logins. How would you investigate it?”Suddenly, knowing the names of ten certifications does not help much. This is an uncomfortable truth about starting a cybersecurity career: Certifications can demonstrate that you studied something. They do not automatically prove that you can do the job. The cybersecurity industry does not need more people who can simply list security concepts. It needs people who can think, investigate, understand systems, and respond to problems. So, if you are trying to enter cybersecurity, stop asking yourself: “Which certification should I do next?”Start asking: “Which skills would make me useful in a real security team?” Here are five skills that matter far more than most beginners realise. 1. Networking Fundamentals: You Cannot Secure What You Do Not Understand Let’s start with the foundation. You do not need to become a network engineer to work in cybersecurity. But you absolutely need to understand how networks work. A surprising number of cybersecurity beginners try to learn advanced tools before understanding basic networking concepts. They know the name of a SIEM. They have seen an EDR dashboard. They can explain what a firewall does. But ask them to explain the difference between TCP and UDP, or what happens when a user visits a website, and the answer becomes uncertain. This creates a serious problem. Imagine an alert showing suspicious outbound traffic from an internal workstation. How do you determine whether it is malicious? You need to understand: Without this foundation, you are simply looking at an alert. You are not investigating it. Networking knowledge helps you understand the story behind the data. And cybersecurity is largely about understanding stories. What happened? Where did it start? What did it communicate with? What changed? A strong cybersecurity professional does not just say, “There is suspicious traffic.” They ask: “Why is this system communicating with that destination, over that port, at this time?” That is the beginning of real security thinking. 2. Log Analysis: Learn to Read What Systems Are Telling You Security teams generate an enormous amount of data. Login events. Firewall logs. Endpoint alerts. Authentication records. Cloud activity. Application events. The problem is not a lack of information. The problem is understanding what information actually matters. This is where log analysis becomes one of the most important skills in cybersecurity. Consider this: A user successfully logged in at 10:00 AM. On its own, this is completely normal. Now add a few more events: Suddenly, the individual events tell a very different story. The skill is not simply reading logs. The skill is connecting events. A good SOC analyst learns to identify patterns. They ask: This is why someone with strong analytical skills can sometimes outperform someone with more certifications. Because cybersecurity is not a multiple-choice exam. In the real world, the answer is often hidden across hundreds of events. You need to know how to find it. 3. Understanding Operating Systems: Know What Happens Behind the Interface Many cybersecurity learners focus heavily on tools. But tools are only as useful as your understanding of the systems they monitor. You should understand the basics of operating systems, particularly Windows and Linux. Why? Because attackers interact with operating systems. They create processes. They modify files. They use services. They create accounts. They execute commands. They manipulate permissions. If you do not understand normal system behaviour, malicious behaviour becomes much harder to recognise. For example, imagine an alert showing a suspicious PowerShell command. A beginner may simply see: “PowerShell detected.” An experienced analyst asks: The difference is knowledge. You do not need to memorise every command in Windows or Linux. But you need to understand how systems behave. You need to know what normal looks like. Because in cybersecurity, anomalies only make sense when you understand the baseline. 4. Problem-Solving: Cybersecurity Is Not a Checklist This may be the most underrated cybersecurity skill. Cybersecurity rarely gives you a perfectly labelled problem. You will not always receive an alert saying: “This is a phishing attack. Please follow steps 1 to 5.” Real incidents are messy. Information may be incomplete. The alert may be misleading. Multiple systems may be involved. And sometimes, the first assumption is completely wrong. This is why problem-solving matters. A strong cybersecurity professional is comfortable asking: “What else could explain this?” For example, a suspicious login could be: The job is not to immediately label everything as an attack. The job is to investigate. Good problem-solving means: This is also why cybersecurity professionals should not be afraid of saying: “I don’t know yet.” The important word is yet. The ability to investigate and find the answer is more valuable than pretending to know everything. 5. Communication and Documentation: The Skill Nobody Talks About Enough Cybersecurity is technical. But cybersecurity is also communication. You may investigate an incident perfectly. You may identify the root cause. You may even contain the threat. But if you cannot clearly explain what happened, your work loses value. A security analyst may need to communicate with: And each audience needs a different level of explanation. A CISO may not need to know every command executed on a system. But they need to know: What happened? What was affected? What is the business impact? What is being done about it? This is where clear documentation matters. A good incident report should help someone understand the incident even if they were not part of the investigation. Poor documentation creates confusion. It also makes future investigations harder. In cybersecurity, your
The Kudankulam Data Breach: What India’s Critical Infrastructure Can Teach Us About Third-Party Risk
The most dangerous assumption in cybersecurity is that your security ends at your firewall. On 15 July 2026, a report about India’s Kudankulam Nuclear Power Plant created a wave of concern across the cybersecurity and critical infrastructure community. A ransomware group reportedly published a large cache of files on the dark web that were allegedly linked to Reliance Group and related to infrastructure work at Kudankulam’s Units 3 and 4. According to reporting, the data was associated with a server hosted by Yotta, a third-party data centre provider. Reliance acknowledged a partial breach of its data and said the government had been informed. The reported files included purported blueprints, supplier details, inspection records and other project-related documents. The authenticity of the documents and the full extent of the exposure remain under investigation. Let us be precise about something. This is not a story about an attacker remotely taking control of a nuclear reactor. And that distinction matters. The Indian government had previously stated, in relation to the 2019 KKNPP malware incident, that the infection was limited to the administrative network and that the plant’s control and instrumentation systems were isolated from external and administrative networks. But here is the uncomfortable lesson: An organisation does not need to lose control of its most critical system for a cyber incident to become strategically dangerous. Sometimes, the breach happens somewhere else. With someone else. On infrastructure you do not directly operate. And yet the information exposed may still be connected to your most sensitive assets. That is the real third-party risk lesson emerging from the Kudankulam case. The breach did not have to start inside the nuclear plant When people hear “critical infrastructure cybersecurity,” they usually imagine the obvious attack scenario. An attacker finds a vulnerability in a plant network. They bypass a firewall. They gain access to an OT environment. They compromise an industrial control system. The story is easy to understand because the attack follows the traditional perimeter model. But modern attacks do not always work that way. The Kudankulam case, as currently reported, presents a different and much more uncomfortable model. The reported chain looks something like this: Critical infrastructure project → contractor → third-party data centre → stored project data → ransomware attack → public exposure The attacker may not need to breach the nuclear facility directly. They may not need access to a reactor control system. They may not even need to understand the entire plant architecture. They may only need to find a connected organisation holding sensitive information related to the project. This is the fundamental shift in third-party risk. Your attack surface is no longer defined by the systems you own. It is defined by the systems that hold your data, connect to your operations, support your projects, or are trusted by your people. The data may be “administrative”. The intelligence may not be. One of the most dangerous words in cybersecurity is administrative. An administrative system is often mentally categorised as less important than an operational system. That is understandable. An office network is not a reactor control system. A project document is not a PLC. A supplier database is not a safety system. But attackers do not always look at data through the same lens as defenders. A document that looks “administrative” to an organisation may provide an adversary with context. Supplier information can reveal dependencies. Inspection records can reveal equipment and maintenance patterns. Project documents can reveal how different organisations interact. Engineering documentation can reveal design assumptions or infrastructure relationships. Insurance documents can expose how an organisation categorises and financially models certain risks. Individually, each document may appear harmless. The problem is aggregation. A threat actor does not necessarily need one magical document. They may need thousands of small pieces of information that, when combined, create a much clearer picture of the target. This is why data classification cannot be based only on the question: “Can this file directly control a critical system?” The better question is:“What could an adversary understand if they collected enough of our data?” The vendor is not “just a vendor” anymore For years, many organisations have treated third-party risk as a procurement activity. A vendor is selected. A questionnaire is sent. A certificate is requested. A contract is signed. The vendor is onboarded. And the security team moves on to the next problem. This approach is increasingly inadequate. NIST describes cybersecurity supply chain risk management as the process of identifying, assessing and mitigating risks across the interconnected ICT and OT supply chain throughout the lifecycle of systems and services. That lifecycle includes design, development, deployment, maintenance and even destruction. That is a very different way of thinking about vendors. A vendor is not simply a company that provides a service. A vendor is a security dependency. And every security dependency creates a question: What happens to our risk when our data, access or operations move into their environment? In the Kudankulam case, the reported involvement of a third-party data centre provider is precisely what makes the story relevant to almost every modern organisation. Because most companies today rely on someone else. Cloud providers. Managed service providers. Data centres. SaaS platforms. Payroll systems. IT support vendors. Consultants. Engineering contractors. Software suppliers. And increasingly, AI platforms. The perimeter is no longer a wall. It is an ecosystem. The “weakest link” analogy is no longer enough Cybersecurity professionals often say: “Your security is only as strong as your weakest link.” It sounds correct. But it is incomplete. The problem is that third-party risk is not always about finding the weakest vendor. It is about understanding where trust has been transferred. A highly mature organisation may have excellent internal controls. Strong MFA. A capable SOC. Endpoint detection. Segmentation. Incident response. But if a critical supplier has access to sensitive project data and operates with weaker controls, the risk does not disappear simply because the primary organisation is mature. In fact, attackers may deliberately target the supplier. NIST has explicitly highlighted that
Vishwadeep S***********
Senior Network Security Manager
Mazhar A****
Cybersecurity Consultant
Ayush S*****
Network Security Custom Training – W****** B******* S***** (WBS)
Mukul S*****
System Integration Advisor